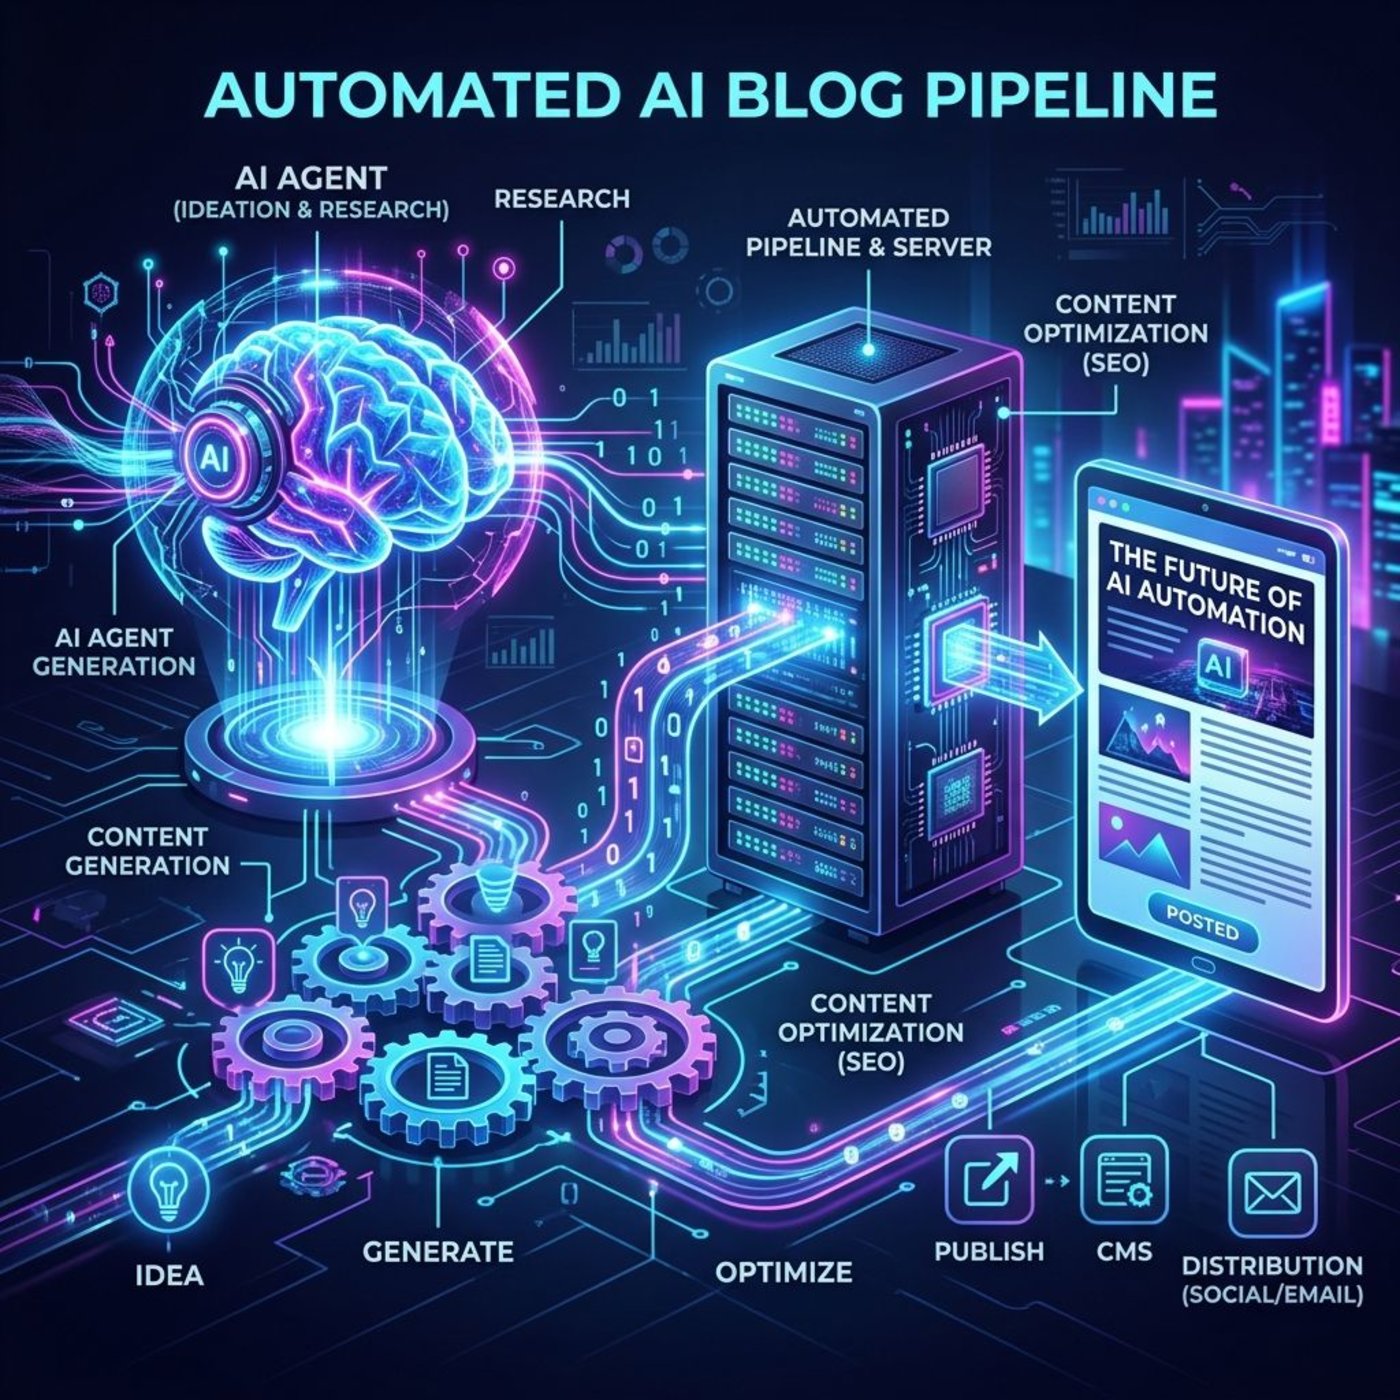
How I Built a Fully Automated, AI-Powered Blog Pipeline
Creating consistent, high-quality technical content can be a major challenge when you're balancing a full-time engineering career. To solve this, I decided to over-engineer a solution: a fully automated, scheduled blog pipeline that writes, formats, and publishes technical articles entirely on its own.
In this post, I'll break down the architecture of how my portfolio automatically generates and publishes SEO-friendly blog posts using Next.js, GitHub Actions, and Groq.
The Architecture Overview
The pipeline is built on a simple philosophy: let the AI do the heavy lifting, but keep the structure and deployment grounded in traditional software engineering.
Here are the moving parts:
GitHub Actions (The Cron Job): Triggers the script on a schedule.
Node.js Generation Script: The brain that orchestrates data fetching, LLM prompting, and markdown processing.
Groq (Llama 3.3 70B): The LLM that writes the content.
Next.js API Routes: The secure endpoints that receive the generated blog and save it to the database.
1. Grounding the AI (Preventing Hallucinations)
The biggest risk of AI-generated content is generic, hallucinated fluff. To prevent this, the script first loads a grounding context file (llms.txt). This file contains my real resume, technology stack, and past projects.
Before generating a new post, the script also fetches all my existing blog titles from the database. It feeds this entire context to the LLM, instructing it to pick a fresh topic from a predefined list of architectural "pillars" and write specifically about my real-world experience.
2. Structured Outputs with XML
Initially, I asked the LLM to return a massive JSON object containing the title, slug, and a 1,000-word markdown string. This failed miserably. LLMs are notoriously bad at escaping long, multi-line strings in JSON, resulting in broken parses.
The fix? XML tags. I updated the prompt to output a simple, un-fenced structure:
xml<title>My Title</title>
<slug>my-title-slug</slug>
<excerpt>A short summary...</excerpt>
<markdown>
# My Title
The blog body here...
</markdown>
Using a simple regular expression, the Node script cleanly extracts these fields every single time with zero parsing errors.
3. Safe HTML Processing
Once the markdown is generated, it cannot be blindly trusted. The script uses the unified ecosystem (remark-parse, remark-rehype, rehype-sanitize, and rehype-stringify) to parse the markdown, strip out any potentially malicious scripts or malformed HTML, and compile it into a safe, render-ready HTML string.
4. Secure API Ingestion
How does a GitHub Action securely post to a Next.js application without a browser session?
I implemented a dual-authentication pattern on the POST /api/blogs route. The route accepts either:
A standard Admin session cookie.
An
Authorization: Bearer <TOKEN>header.
The Node script running in GitHub Actions passes a secure, 32-byte BLOG_AUTOMATION_TOKEN via the header. To prevent timing attacks, the backend uses Node's timingSafeEqual to verify the token. I also added a global ENABLE_BLOG_AUTOMATION environment flag as a master kill-switch.
5. Publishing and Push Notifications
Finally, the Next.js API inserts the sanitized HTML into a serverless Postgres database (Neon) using Drizzle ORM.
If the environment variable AUTO_PUBLISH is set to true, the script immediately fires a second request to /api/push/send, which blasts a Web Push Notification to all my subscribers informing them that a new article just went live.
Conclusion
By combining the lightning-fast inference of Groq with the reliability of GitHub Actions and Next.js, I now have a blog that runs itself. It writes grounded, technical content, securely authenticates its own API requests, and notifies my readers—all while I'm asleep.
Discussion (0)
No comments yet. Be the first to share your thoughts on this architecture!